publications
2026
-
 Rethinking the Design Space of Vanilla Pixel Diffusion TransformersUnder Submission, Sep 2026
Pixel-space diffusion models have recently re-emerged as a compelling alternative to latent diffusion, avoiding the lossy latent bottleneck and separately trained autoencoder. JiT shows that a vanilla diffusion transformer can generate directly in pixel space by replacing the commonly used velocity prediction (v) with clean image prediction (x0). In this work, we revisit this choice and introduce Mꜰʟᴏᴡ, an adaptive parameterization that learns to interpolate between x0 and v prediction across principal directions of the data, which can be learned end-to-end with diffusion model training. We find that the preferred parameterization varies systematically with the data representation and model capacity. Notably, increasing model capacity shifts preference toward v prediction from x0 prediction. We evaluate Mꜰʟᴏᴡ across ImageNet, UCF-101 video, and large-scale text-to-image generation, demonstrating competitive or improved generative performance across diverse settings. In addition, we find that vanilla pixel diffusion transformers, irrespective of parameterization, retain a persistent high-frequency deficit relative to real images. To address this, we introduce ConvRefiner, a lightweight convolutional module trained post-hoc with adversarial loss while keeping the diffusion backbone frozen. With only a small amount of additional training, ConvRefiner restores the high-frequency statistics of generated images while preserving FID.
-
 Scale Space DiffusionSoumik Mukhopadhyay* , Prateksha Udhayanan*, and Abhinav ShrivastavaIn Proceedings of the Computer Vision and Pattern Recognition Conference (CVPR), Jun 2026
Diffusion models degrade images through noise, and reversing this process reveals an information hierarchy across timesteps. Scale-space theory exhibits a similar hierarchy via low-pass filtering. We formalize this connection and show that highly noisy diffusion states contain no more information than small, downsampled images - raising the question of why they must be processed at full resolution. To address this, we fuse scale spaces into the diffusion process by formulating a family of diffusion models with generalized linear degradations and practical implementations. Using downsampling as the degradation yields our proposed Scale Space Diffusion. To support Scale Space Diffusion, we introduce Flexi-UNet, a UNet variant that performs resolution-preserving and resolution-increasing denoising using only the necessary parts of the network. We evaluate our framework on CelebA and ImageNet and analyze its scaling behavior across resolutions and network depths. Our project website (https://prateksha.github.io/projects/scale-space-diffusion/) is available publicly.
-
 Selective Timestep Weighting and Advantage-Based Replay for Sample-Efficient Diffusion RLHFEric Zhu, Abhinav Shrivastava, and Soumik MukhopadhyayarXiv preprint, (non-archival extended abstract accepted at CVPR 2026 Workshops (GCV, CVEU)), Jun 2026
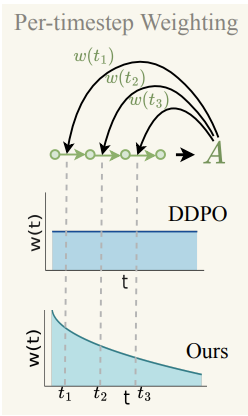
Reinforcement learning from human feedback (RLHF) has emerged as a powerful paradigm for aligning generative models with human preferences. However, applying RLHF to diffusion models remains highly feedback inefficient, as existing approaches typically require large amounts of human or reward model evaluations. This limitation reduces the practicality of diffusion RLHF in realworld settings where feedback is the primary bottleneck. In this paper, we propose two complementary strategies that substantially improve the feedback efficiency of diffusion RLHF while preserving generalization to unseen prompts. Our key observation is that reward information in diffusion trajectories is unevenly distributed: not all denoising timesteps or trajectories contribute equally to learning from a reward signal. By emphasizing informative timesteps and trajectories during optimization, we obtain more effective gradient updates. First, we introduce a per-timestep weighting scheme that reweights denoising steps during policy optimization. We theoretically connect this weighting to the optimal convergence properties of proximal policy optimization (PPO) and approximate the resulting weighting trend empirically. Second, we introduce a replay mechanism that prioritizes informative trajectories, enabling the model to reuse past samples instead of repeatedly querying new rewards. Together, these strategies significantly improve the feedback efficiency of diffusion RLHF. Under identical hyperparameter settings, our approach achieves up to a 6× improvement in sample efficiency compared to widely used diffusion RLHF baselines.


2024
-
 Do text-free diffusion models learn discriminative visual representations?In Proceedings of the European Conference on Computer Vision (ECCV), Sep 2024
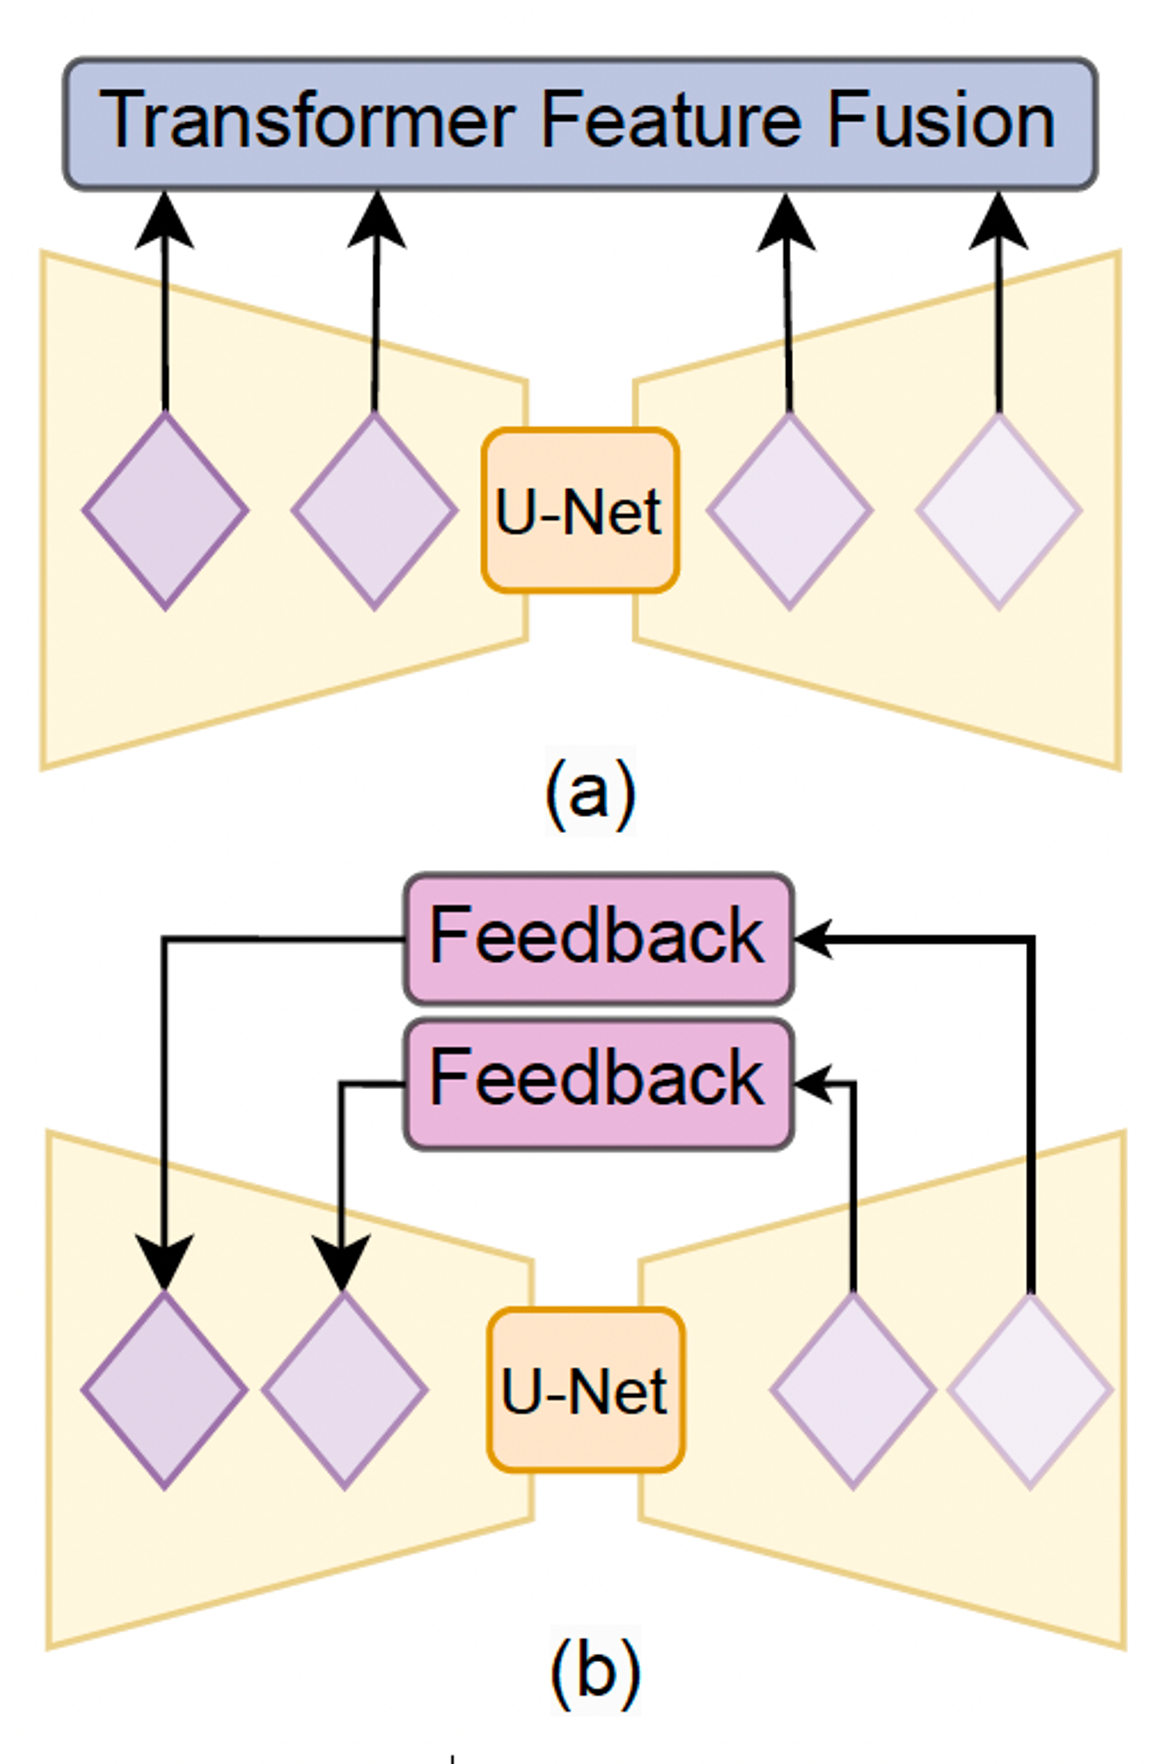
While many unsupervised learning models focus on one family of tasks, either generative or discriminative, we explore the possibility of a unified representation learner: a model which addresses both families of tasks simultaneously. We identify diffusion models, a state-of-the-art method for generative tasks, as a prime candidate. Such models involve training a U-Net to iteratively predict and remove noise, and the resulting model can synthesize high-fidelity, diverse, novel images. We find that the intermediate feature maps of the U-Net are diverse, discriminative feature representations. We propose a novel attention mechanism for pooling feature maps and further leverage this mechanism as DifFormer, a transformer feature fusion of features from different diffusion U-Net blocks and noise steps. We also develop DifFeed, a novel feedback mechanism tailored to diffusion. We find that diffusion models are better than GANs, and, with our fusion and feedback mechanisms, can compete with state-of-the-art unsupervised image representation learning methods for discriminative tasks - image classification with full and semi-supervision, transfer for fine-grained classification, object detection and segmentation, and semantic segmentation.
-
 Diff2Lip: Audio Conditioned Diffusion Models for Lip-SynchronizationIn Proceedings of the IEEE/CVF Winter Conference on Applications of Computer Vision (WACV), Jan 2024
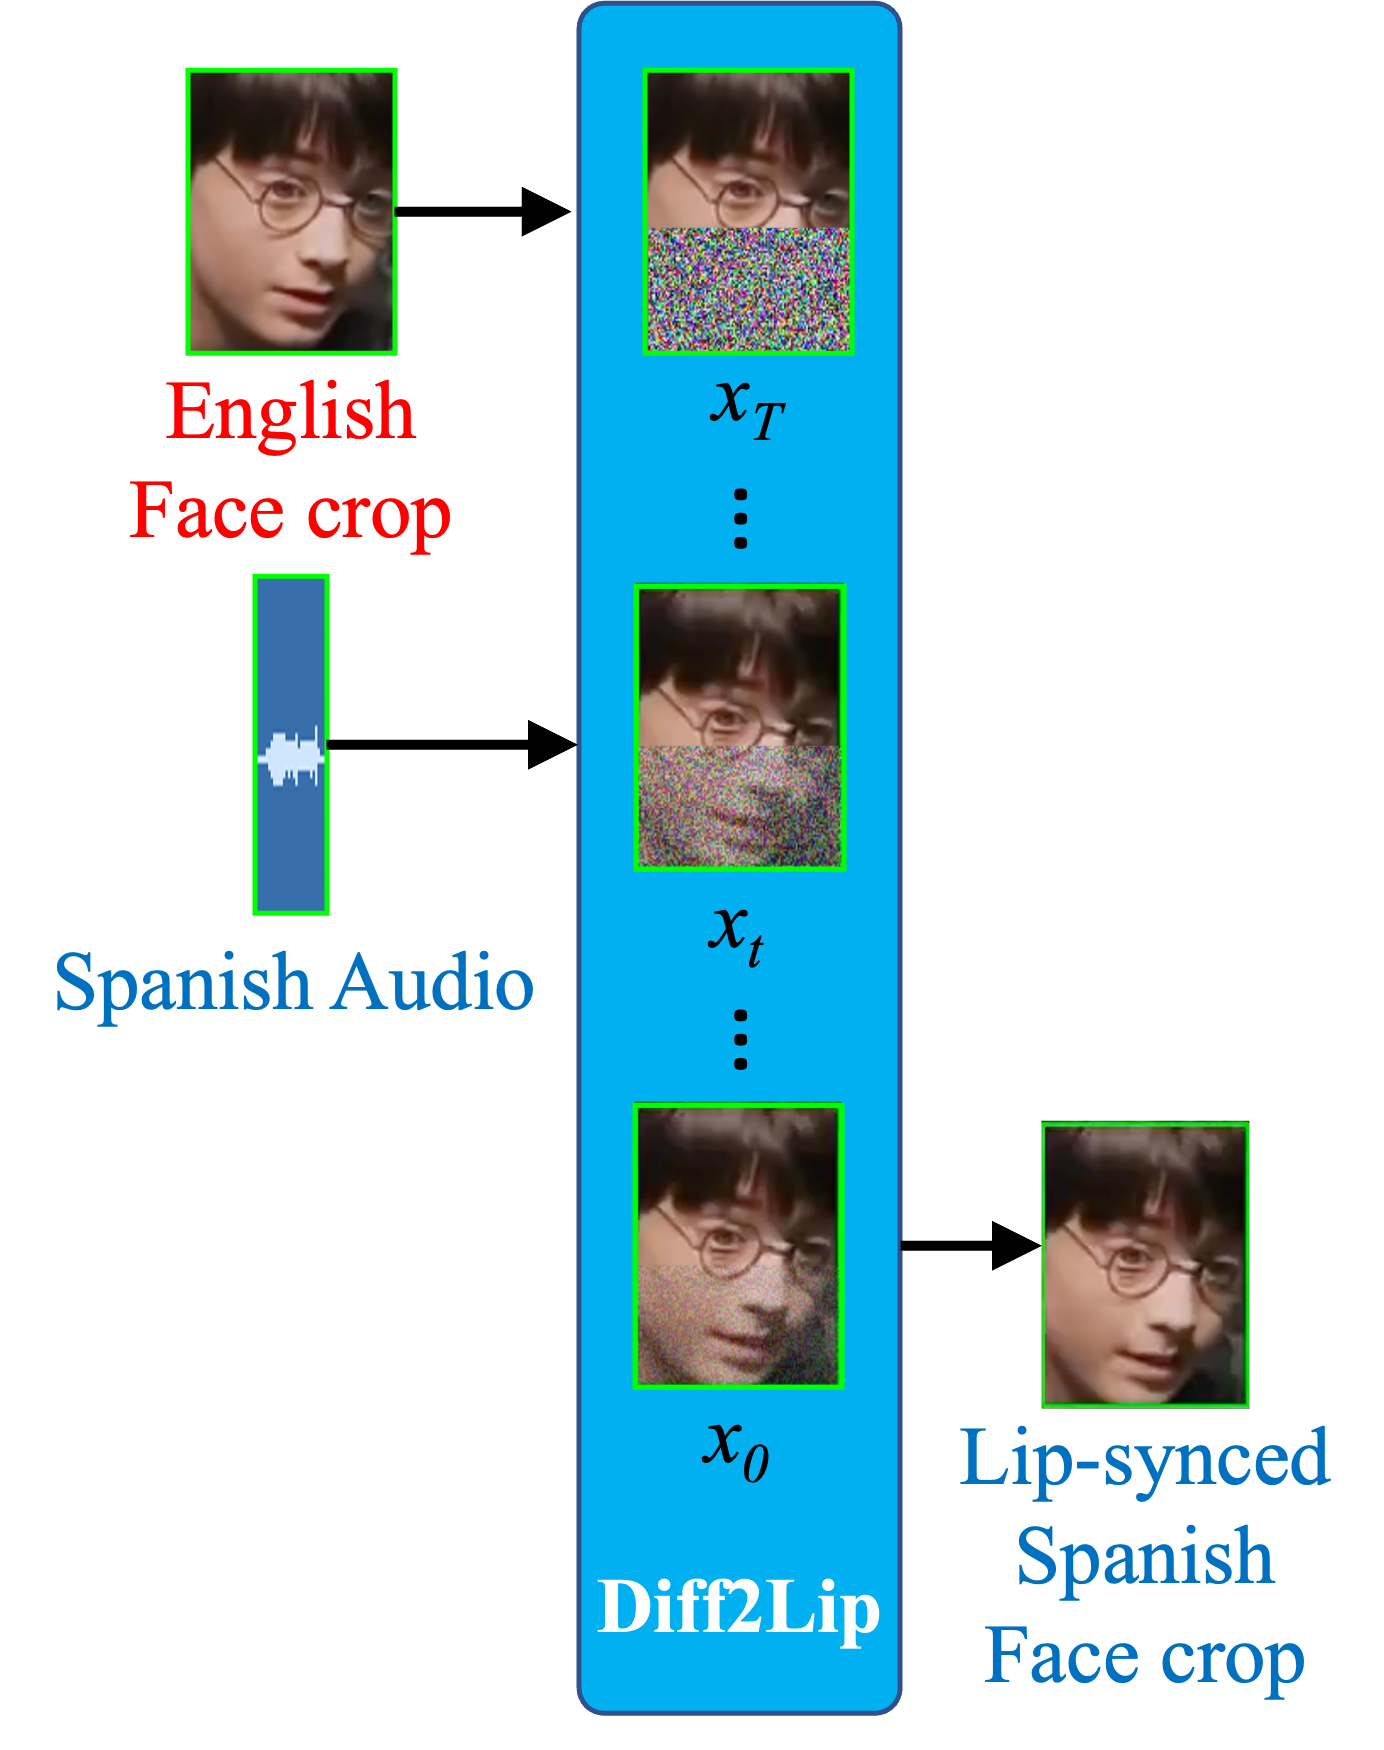
The task of lip synchronization (lip-sync) seeks to match the lips of human faces with different audio. It has various applications in the film industry as well as for creating virtual avatars and for video conferencing. This is a challenging problem as one needs to simultaneously introduce detailed, realistic lip movements while preserving the identity, pose, emotions, and image quality. Many of the previous methods trying to solve this problem suffer from image quality degradation due to a lack of complete contextual information. In this paper, we present Diff2Lip, an audio-conditioned diffusion-based model which is able to do lip synchronization in-the-wild while preserving these qualities. We train our model on Voxceleb2, a video dataset containing in-the-wild talking face videos. Extensive studies show that our method outperforms popular methods like Wav2Lip and PC-AVS in Fréchet inception distance (FID) metric and Mean Opinion Scores (MOS) of the users. We show results on both reconstruction (same audio-video inputs) as well as cross (different audio-video inputs) settings on Voxceleb2 and LRW datasets. Video results and code can be accessed from our project page ( https://soumik-kanad.github.io/diff2lip ).


2023
-
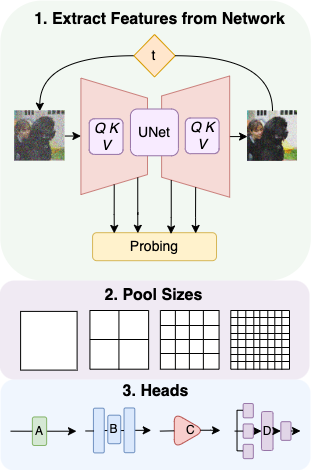 Diffusion Models Beat GANs on Image ClassificationarXiv preprint, Jan 2023
While many unsupervised learning models focus on one family of tasks, either generative or discriminative, we explore the possibility of a unified representation learner: a model which uses a single pre-training stage to address both families of tasks simultaneously. We identify diffusion models as a prime candidate. Diffusion models have risen to prominence as a state-of-the-art method for image generation, denoising, inpainting, super-resolution, manipulation, etc. Such models involve training a U-Net to iteratively predict and remove noise, and the resulting model can synthesize high fidelity, diverse, novel images. The U-Net architecture, as a convolution-based architecture, generates a diverse set of feature representations in the form of intermediate feature maps. We present our findings that these embeddings are useful beyond the noise prediction task, as they contain discriminative information and can also be leveraged for classification. We explore optimal methods for extracting and using these embeddings for classification tasks, demonstrating promising results on the ImageNet classification task. We find that with careful feature selection and pooling, diffusion models outperform comparable generative-discriminative methods such as BigBiGAN for classification tasks. We investigate diffusion models in the transfer learning regime, examining their performance on several fine-grained visual classification datasets. We compare these embeddings to those generated by competing architectures and pre-trainings for classification tasks.

2021
-
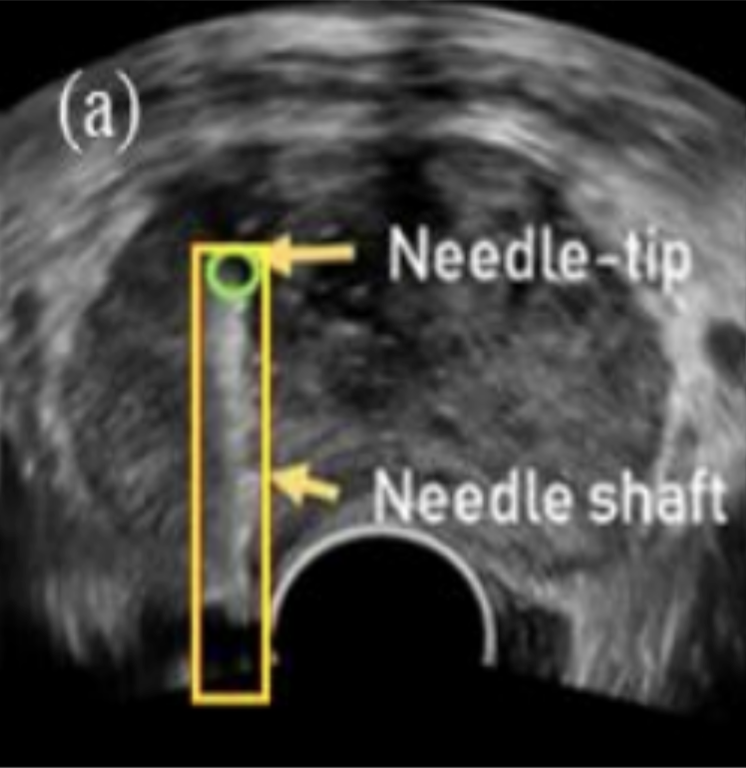 Deep learning based needle tracking in prostate fusion biopsyIn Medical Imaging 2021: Image-Guided Procedures, Robotic Interventions, and Modeling, Jan 2021
Fusion of pre-operative Magnetic Resonance Imaging (MRI) and Trans-Rectal Ultrasound (TRUS) guided biopsy (Fusion Biopsy) has proven to be more effective as compared to cognitive biopsy for the detection of prostate cancer. The detection of the biopsy needle used during the Ultrasound procedure has multiple applications like reporting, repeat biopsy planning and planning therapy. Earlier methods to solve this problem have only used image processing techniques like Hough- Transform or Graph-Cut. These techniques lack robustness because only image-based solution cannot take care of the huge variability in the data as well as the problem of needle going out of plane. Recent deep learning (DL) based solutions for needle detection have high latency and does not exploit temporal information present in TRUS imaging. In this paper, we propose a method to automatically detect the short-lived needle triggers and its position using temporal context incorporated into a DL model termed as Samsung Multi-Decoder Network (S-MDNet). The proposed solution has been tested on 8 patients and yields high sensitivity (96%) and specificity (95%) for the detection of the needle trigger event.

2020
-
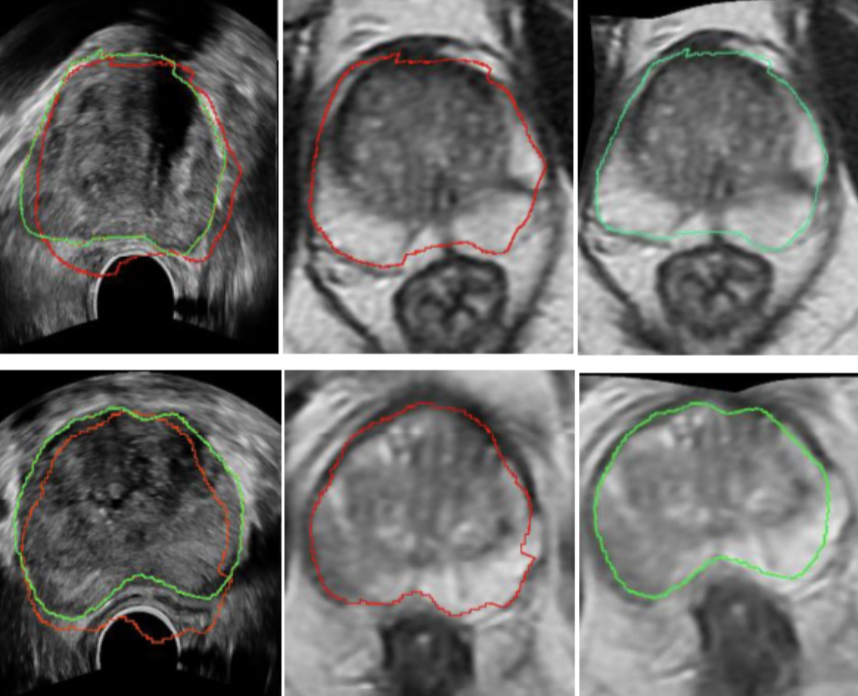 Rigid and deformable corrections in real-time using deep learning for prostate fusion biopsyIn Medical Imaging 2020: Image-Guided Procedures, Robotic Interventions, and Modeling, Jan 2020
Fusion biopsy reduces false negative rates in prostatic cancer detection compare to systemic biopsy. However, accuracy in biopsy sampling depends upon quality of alignment between pre-operative 3D MR and intra-operative 2D US. During live biopsy, the US-MR alignment may be disturbed due to prostate or patient rigid motion. Further, prostate gland deform due to probe pressure, which add error in biopsy sampling. In this paper, we describe a method for real-time 2D-3D multimodal registration, utilizing deep learning, to correct for rigid and deformable errors. Our method do not require an intermediate 3D US and works in real-time with an average runtime of 112 ms for both rigid and deformable corrections. On 12 patient data, our method reduces mean trans-registration error (TRE) from 8.890±5.106 mm to 2.988±1.513 mm, comparable to other state of the arts in accuracy.
